Every box in the lab.
Accounted for.
Model servers, MCP tools and scripts calling AI APIs at 3 a.m. See what every machine in your lab runs, what’s open to the network and where it calls out to.
Open to the LAN?
You’ll know.
It’s easy to leave a model server listening on every interface. GreyArm flags any runtime bound beyond localhost — with the process, address and port — so the only clients are the ones you meant.
Ollama, LM Studio, llama.cpp, Jan and GPT4All — what’s running, on which port, and who else can reach it.
Every Model Context Protocol server, the client that launched it and the tools it was handed.
AutoGPT, CrewAI, LangChain agents, headless browsers and scripts calling AI APIs — caught by what they do, even when they’re not on our list.
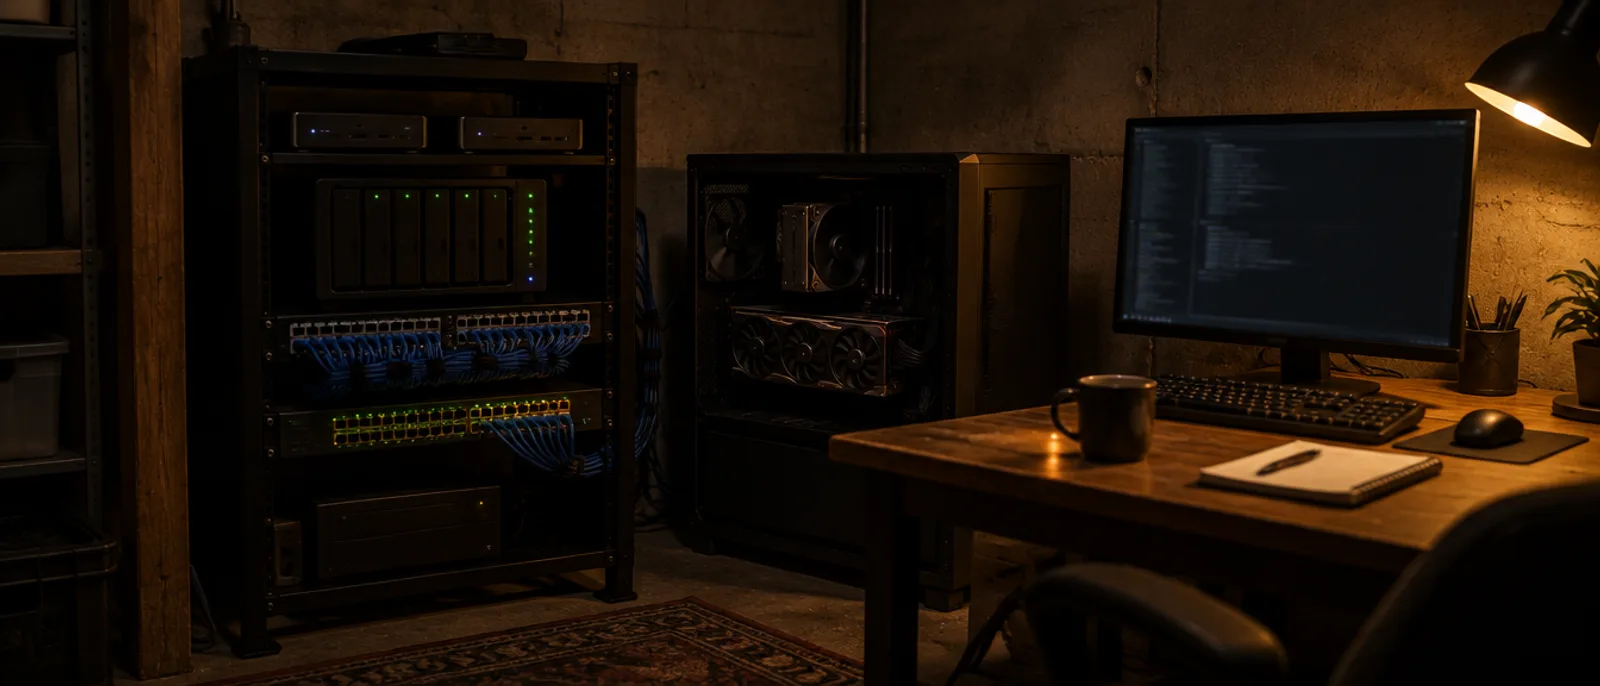
One resolver.
Every box.
Point your router — or just the hosts you care about — at the GreyArm shield. Every AI lookup on the network is logged by device, and you can block providers lab-wide. Everything else goes straight to your upstream resolver.
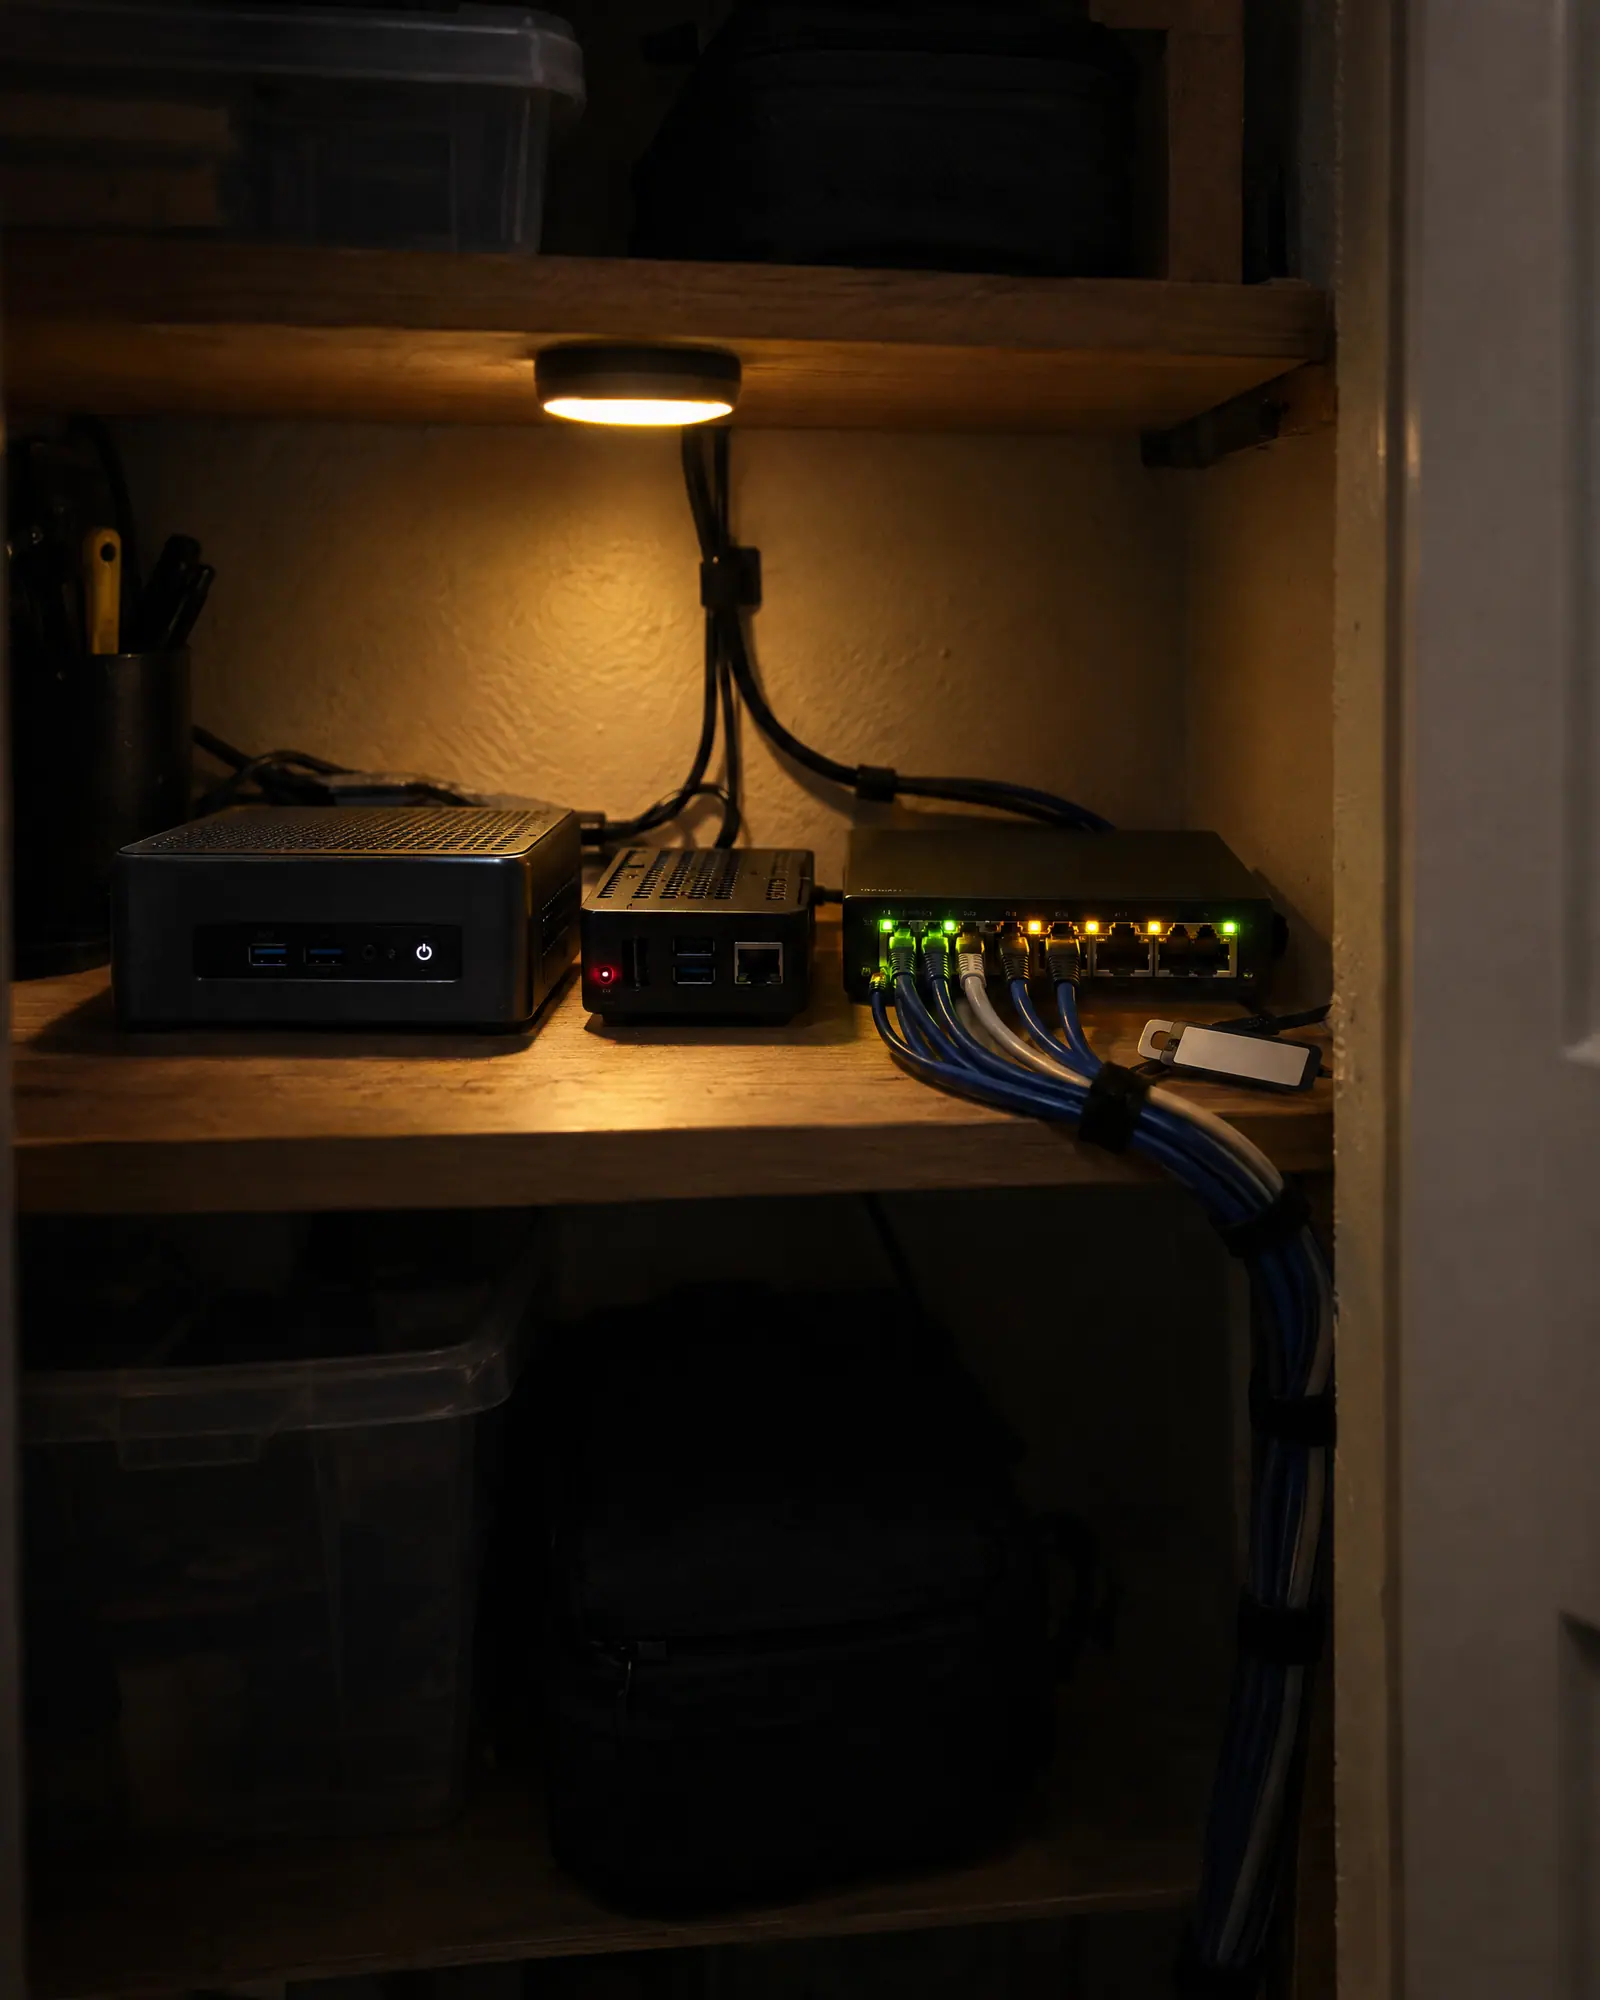
A sensor for
every machine.
Run the sensor on your Linux servers, mini PCs and workstations, link them to one account and see the whole lab in one console — with an alert on your phone when something new starts listening.
- Every agent, with its signer and parent
- Shells and credential access flagged
- Stop a process from anywhere
- Block its AI endpoints or relaunch